Results
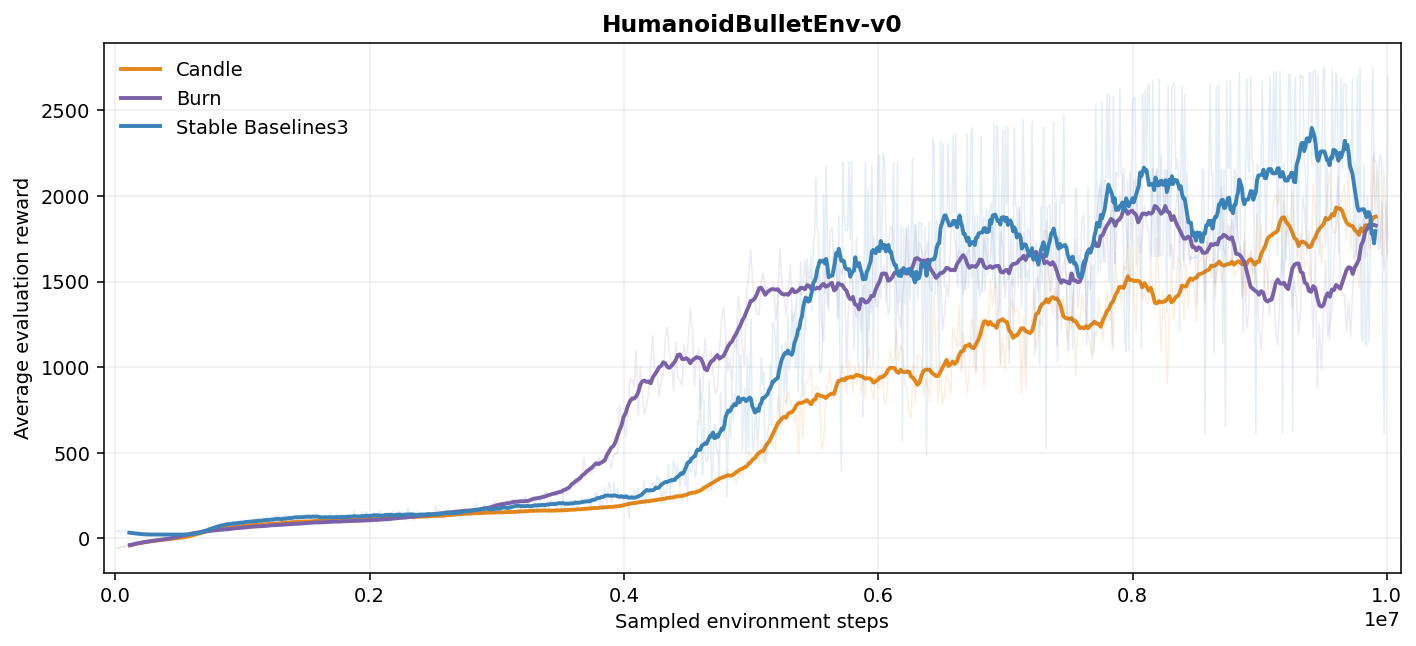
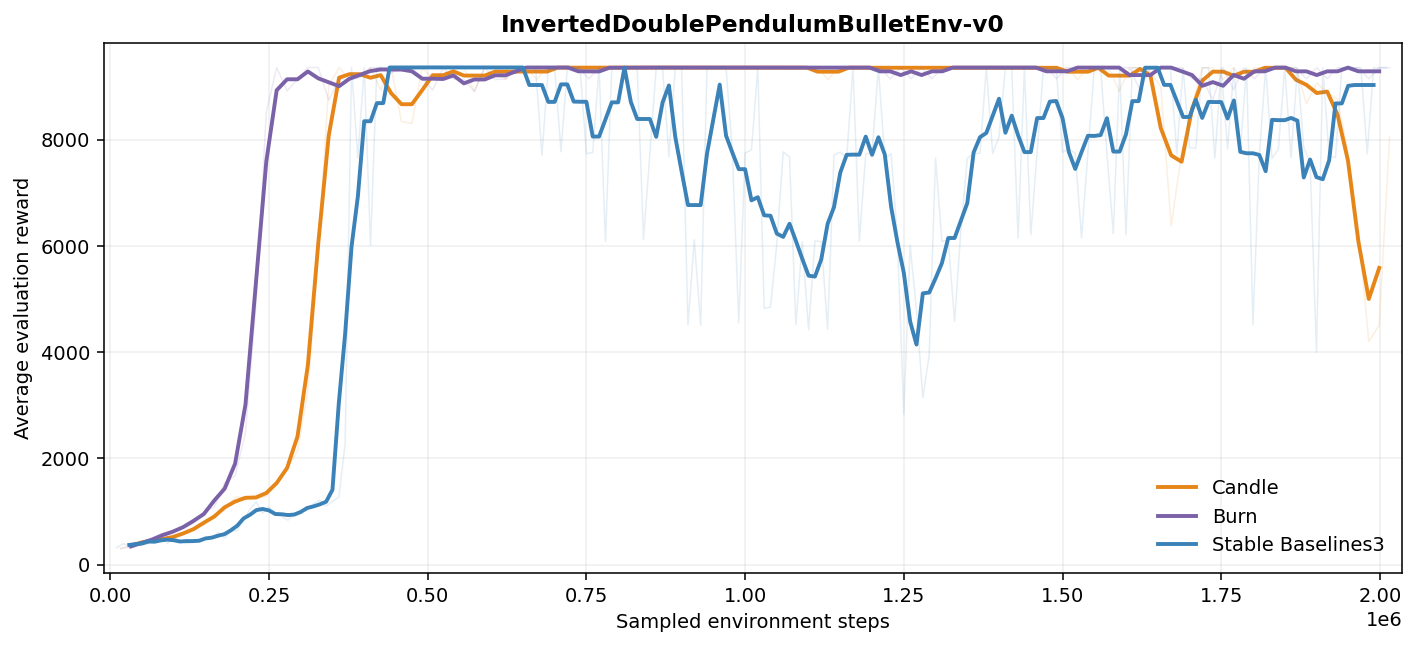
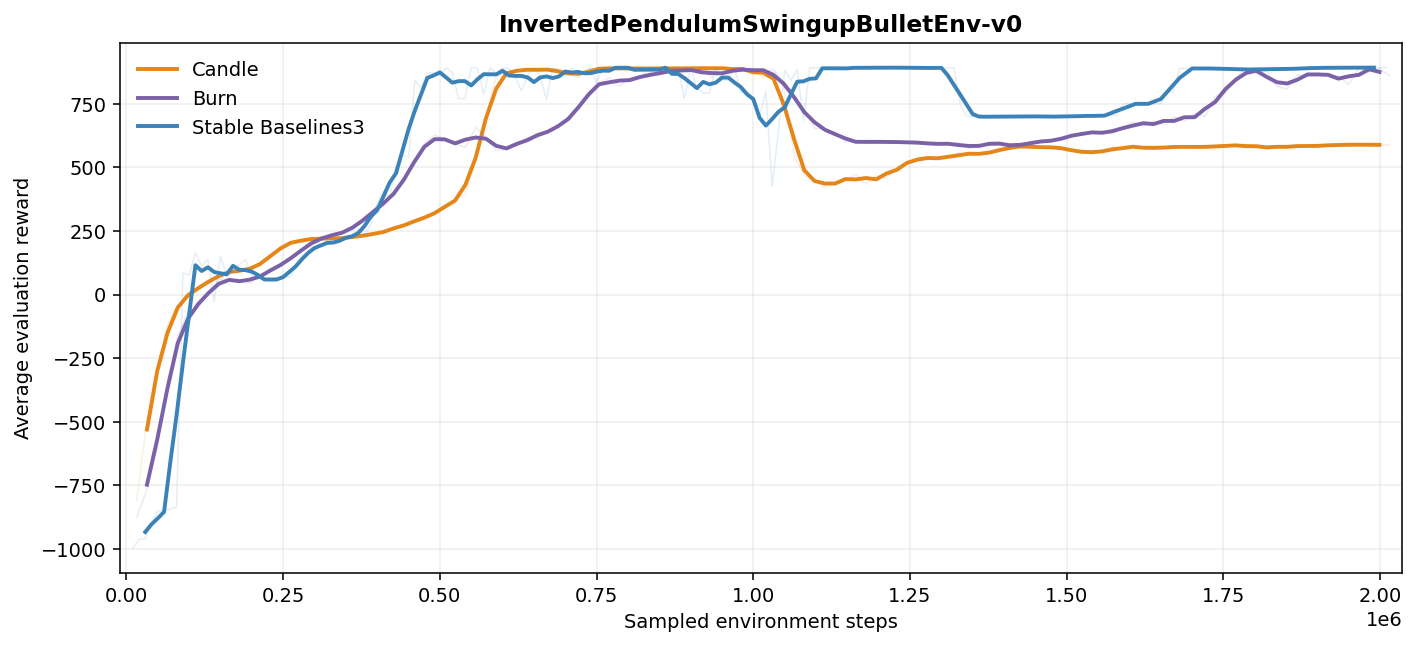
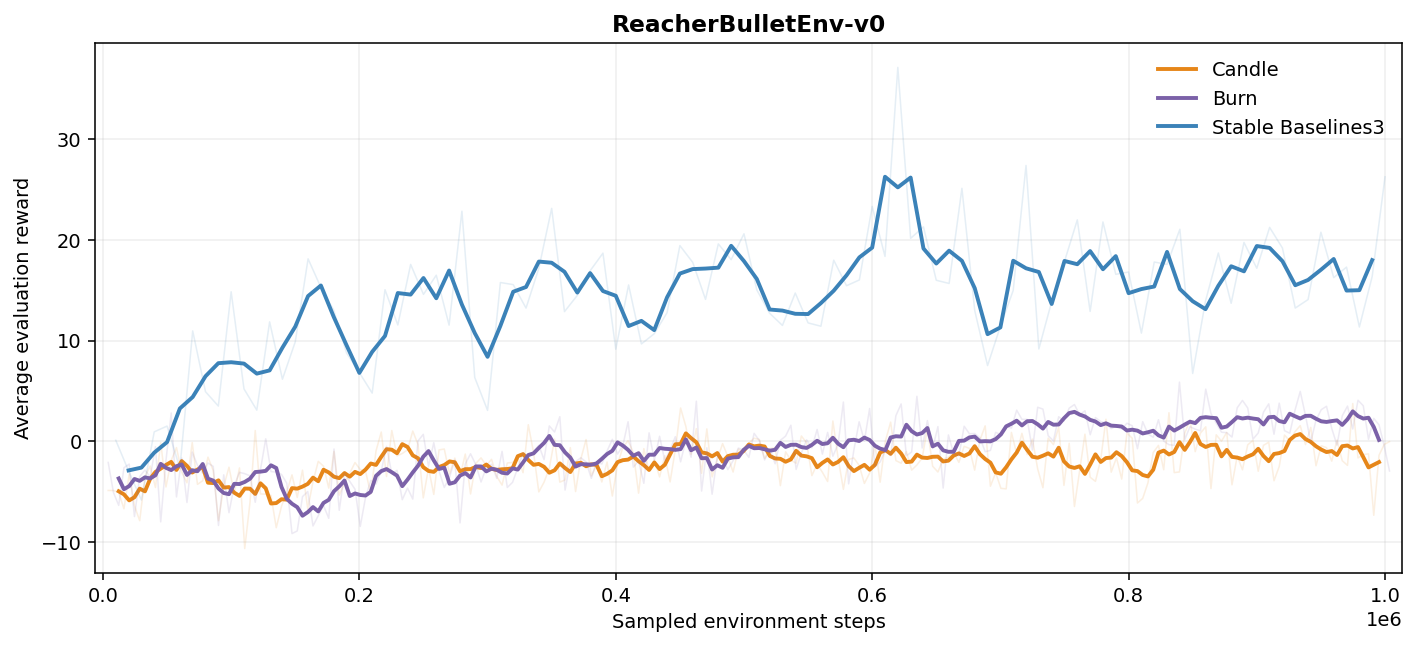
These results are seeded reference runs for r2l’s PPO implementation. They
exercise both supported tensor backends across classic control, Box2D, MuJoCo,
Bullet, and partially observable environments, providing broad integration
coverage and a baseline for identifying behavioral regressions as the
implementation evolves. Each configuration uses seed 0 to reduce variation
between benchmark passes.
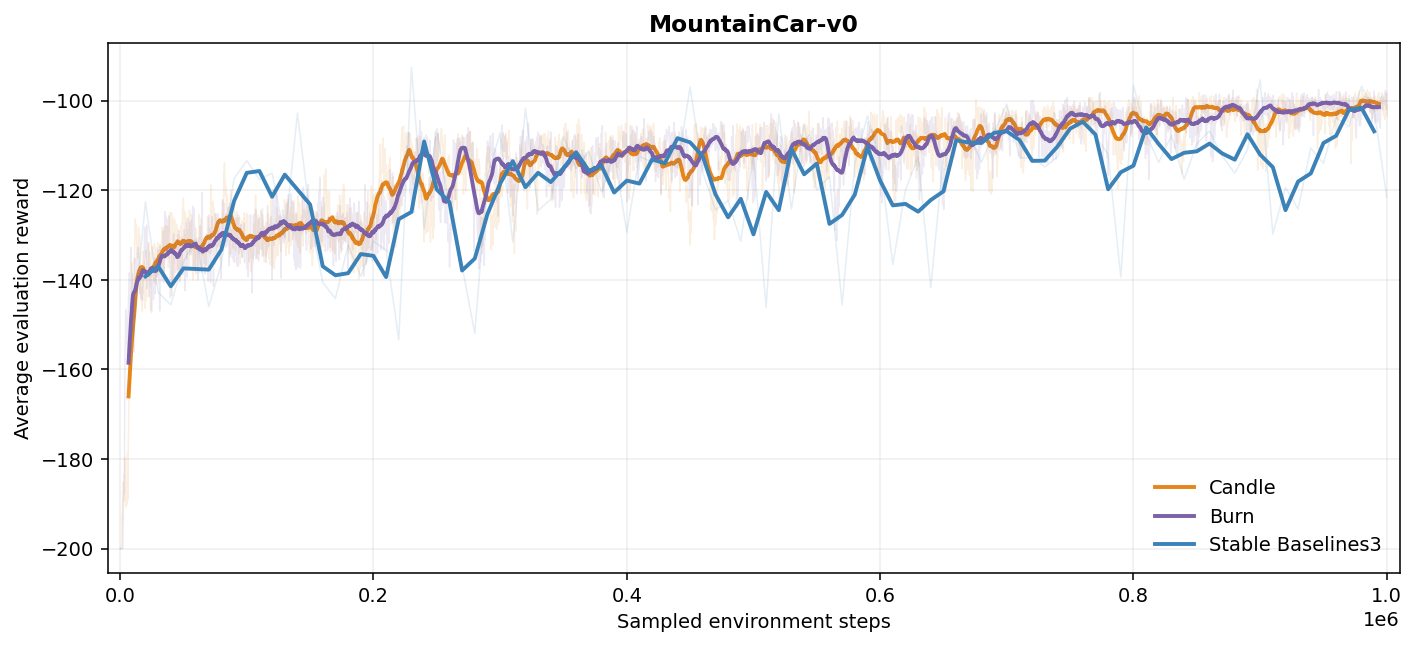
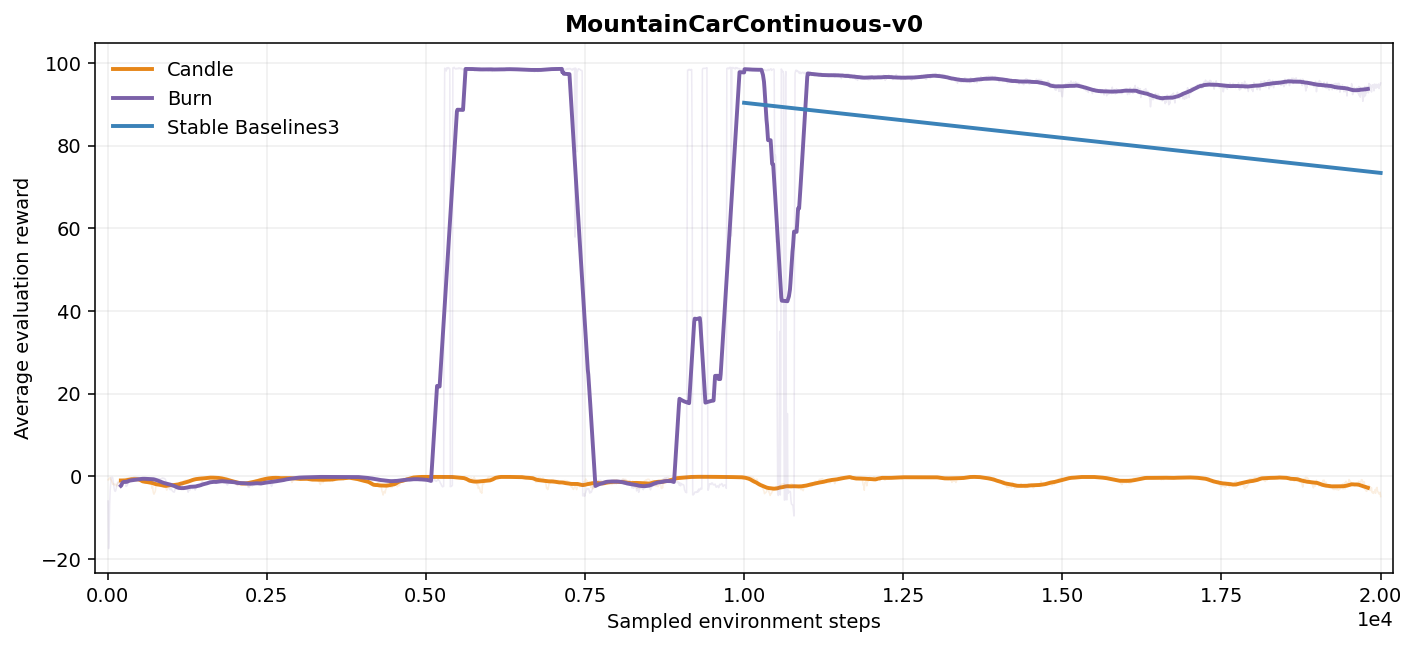
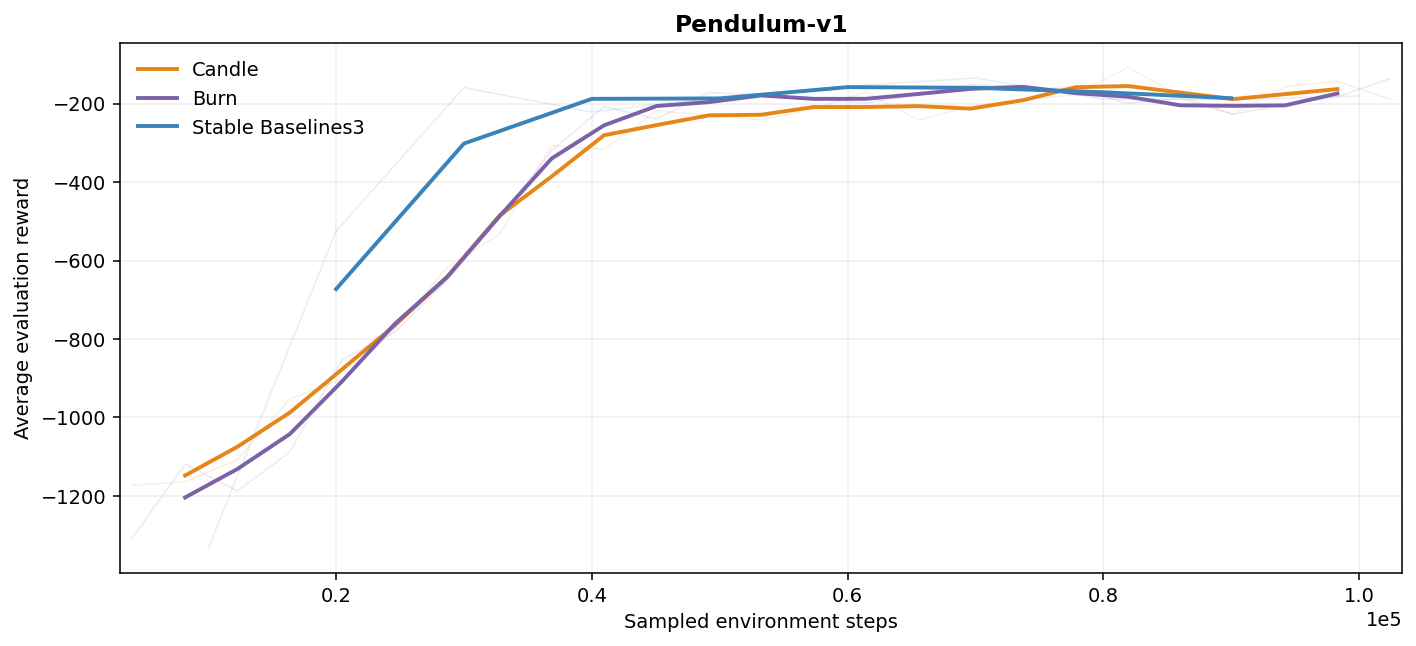
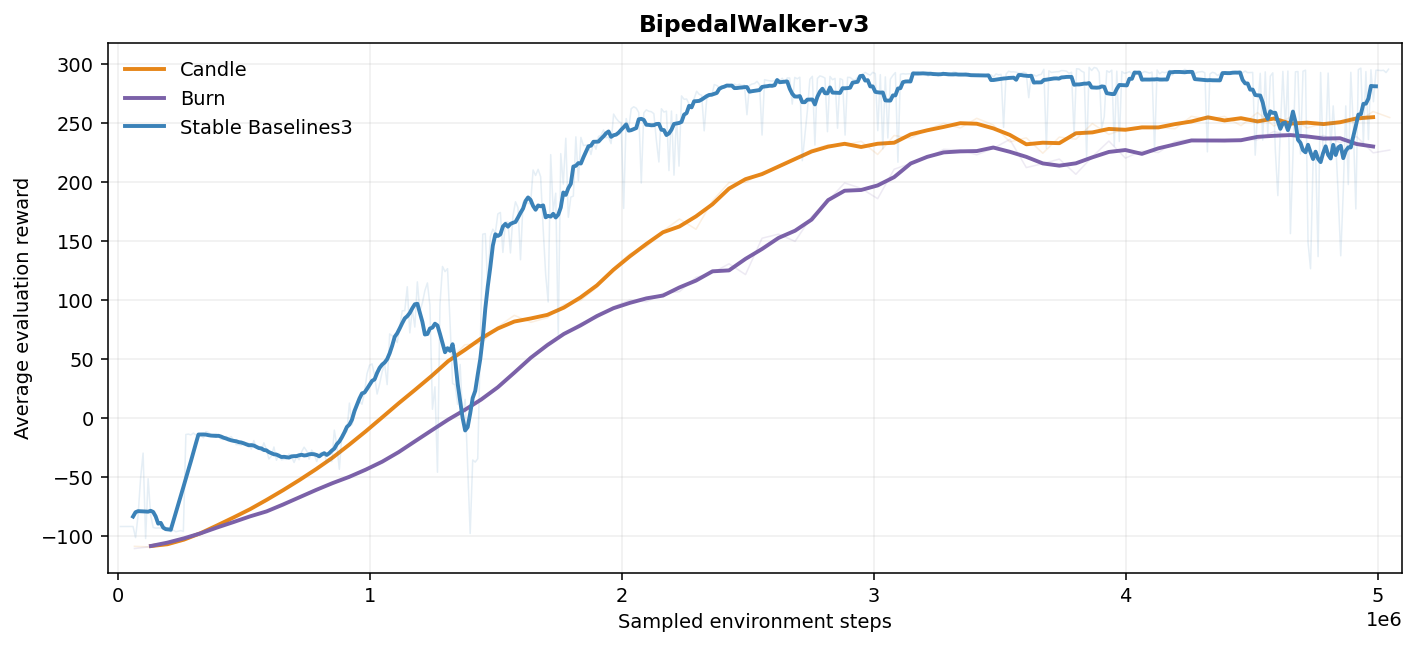
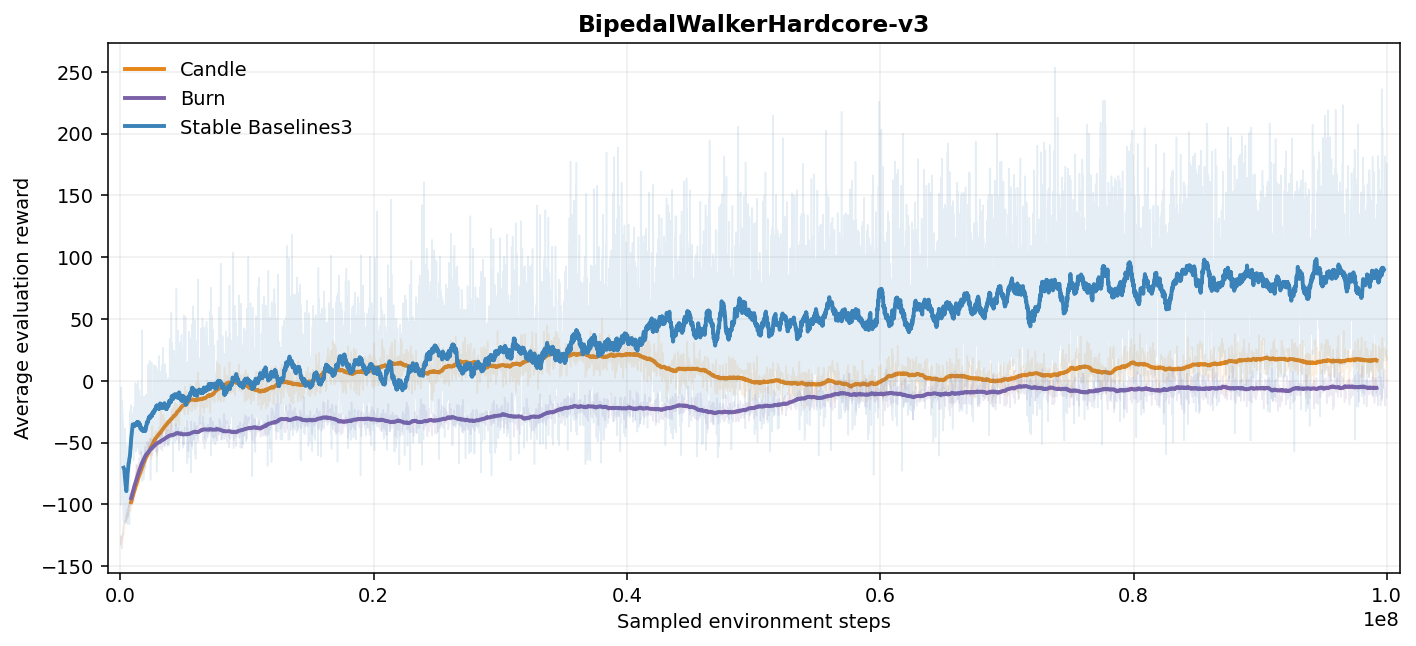
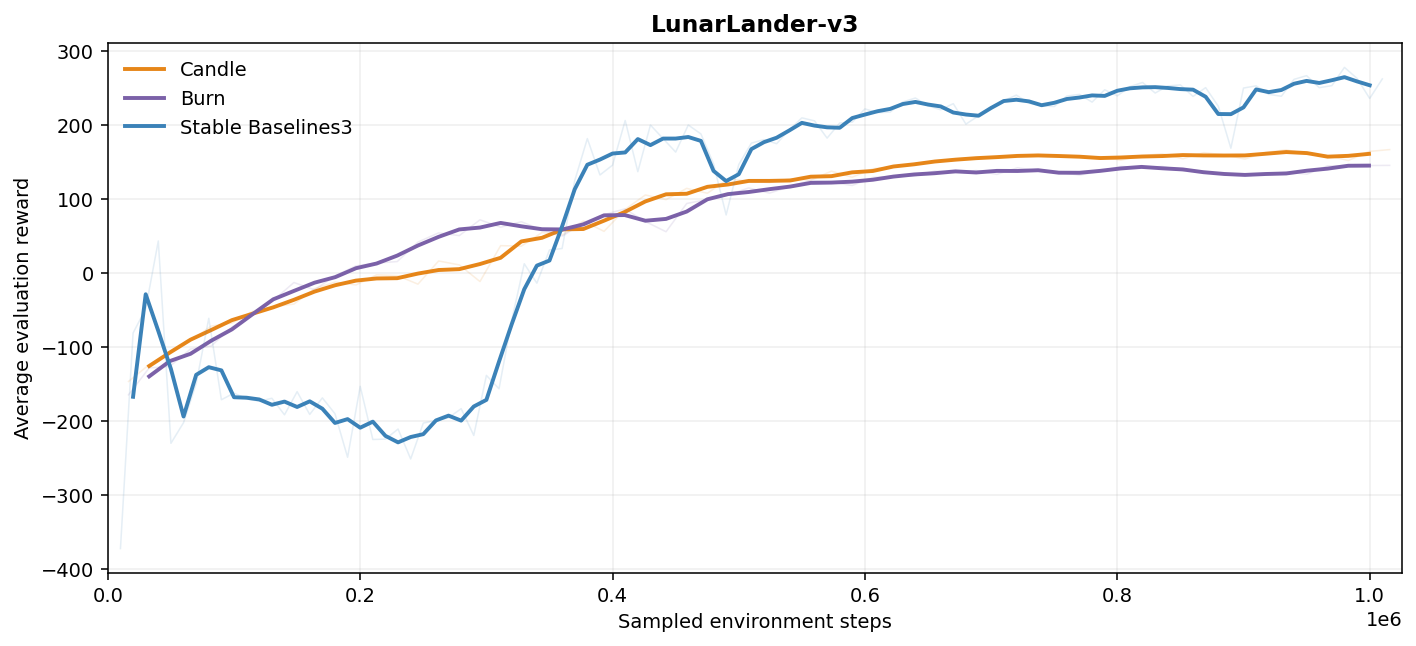
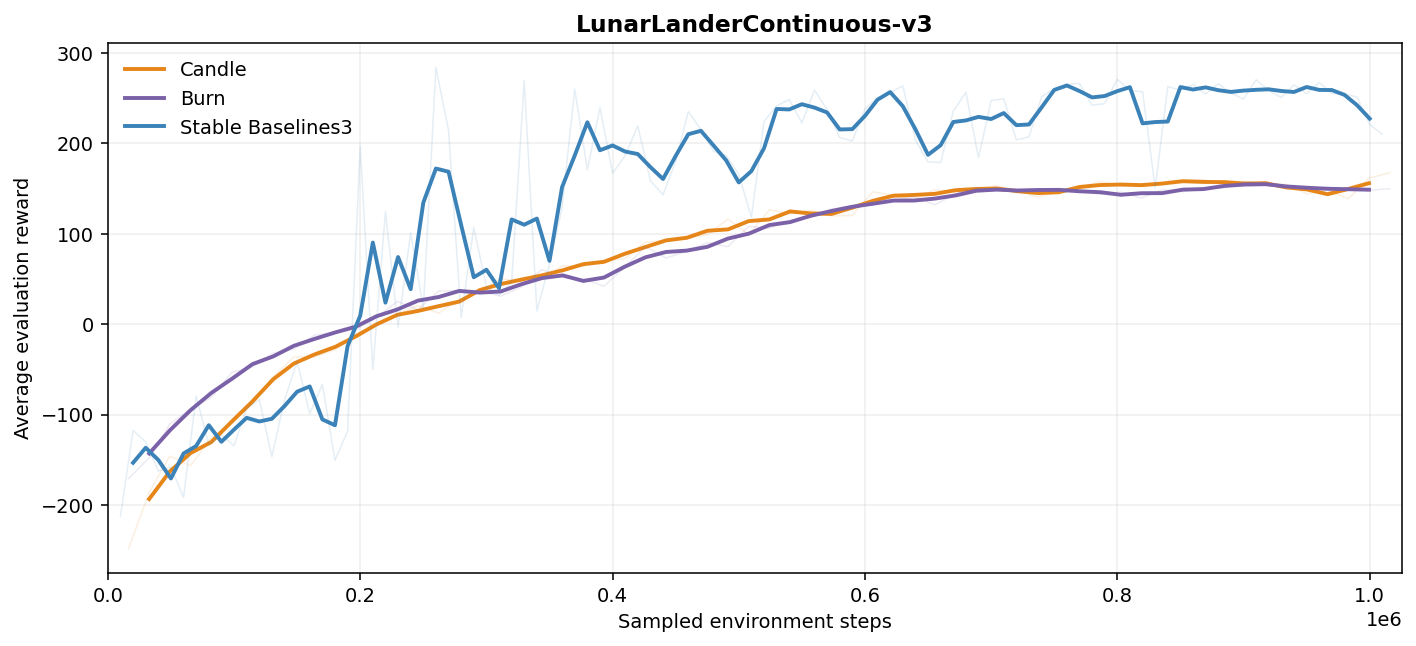
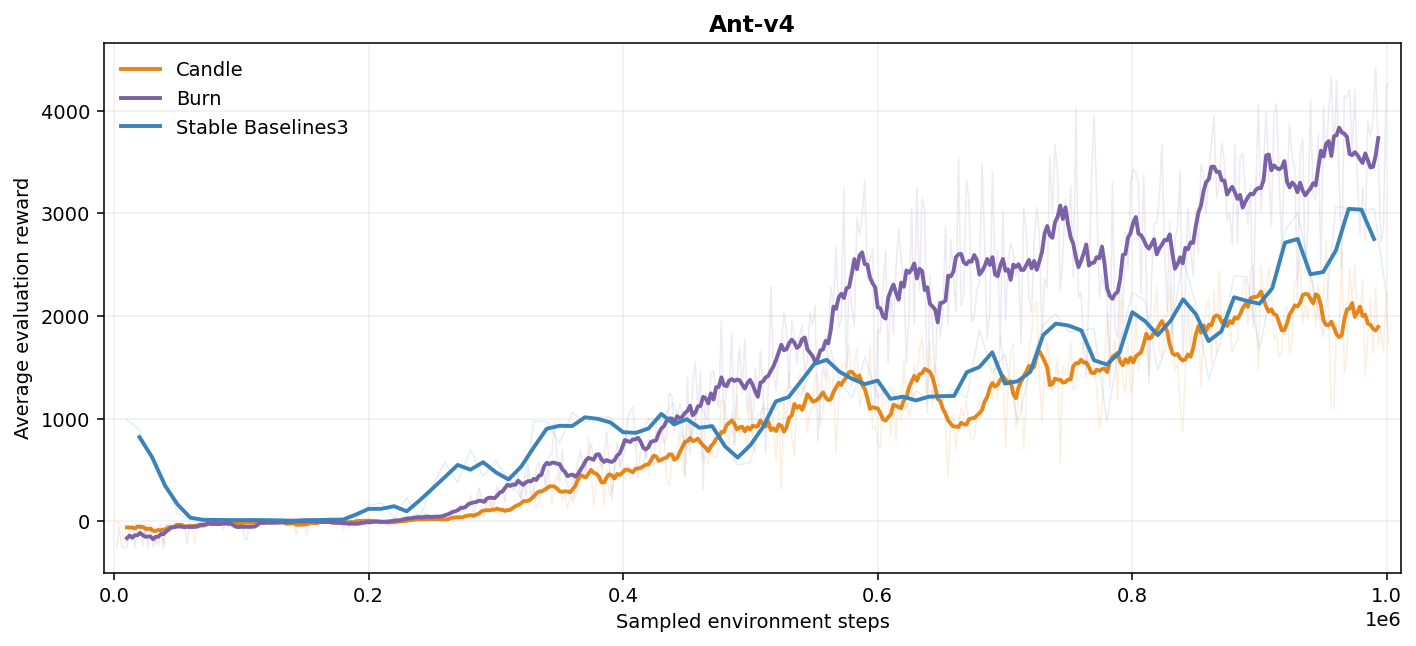
Stable Baselines3 (SB3) curves are included as a familiar external reference. They help make unexpected learning behavior easier to spot and are interesting to compare, but the runs are not designed as a controlled framework ranking.
Setup
All three implementations use the per-environment PPO configurations in the benchmark configuration, which are based on RL Baselines3 Zoo settings. The r2l runs use the same configuration for the Candle and Burn backends. Evaluation follows each implementation’s existing evaluation path.
The runs use r2l 0.0.3 at
commit 6030dd8
and execute as Google Cloud Batch spot jobs in europe-west1 on CPU-only
c4d-highcpu-2 workers. Each task is allocated one vCPU and 1,250 MiB of
memory, with Rayon and OpenBLAS limited to one thread. Up to 36 tasks run
concurrently.
Summary
The current snapshot contains evaluation data for 28 environments on each r2l backend and Stable Baselines3.
| Environment family | Environments |
|---|---|
| Classic control | 5 |
| Box2D | 4 |
| MuJoCo | 10 |
| Bullet | 8 |
| PopGym | 1 |
| Total | 28 |
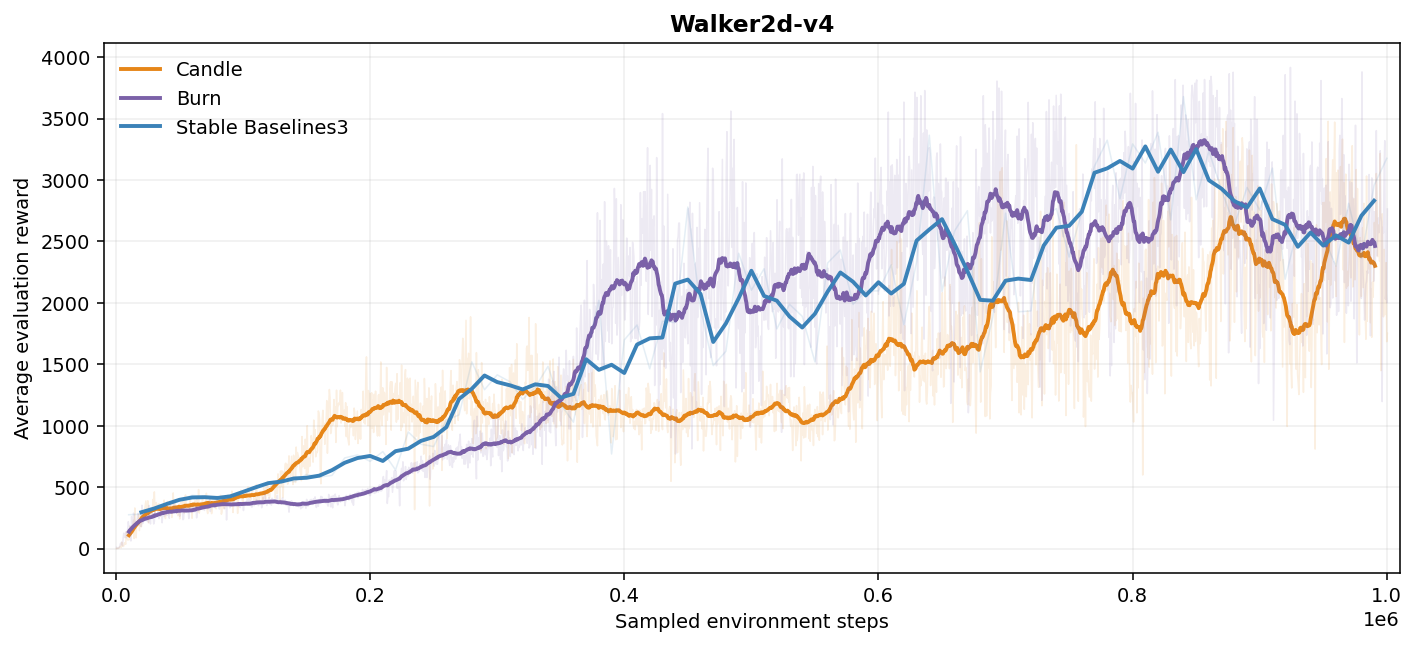
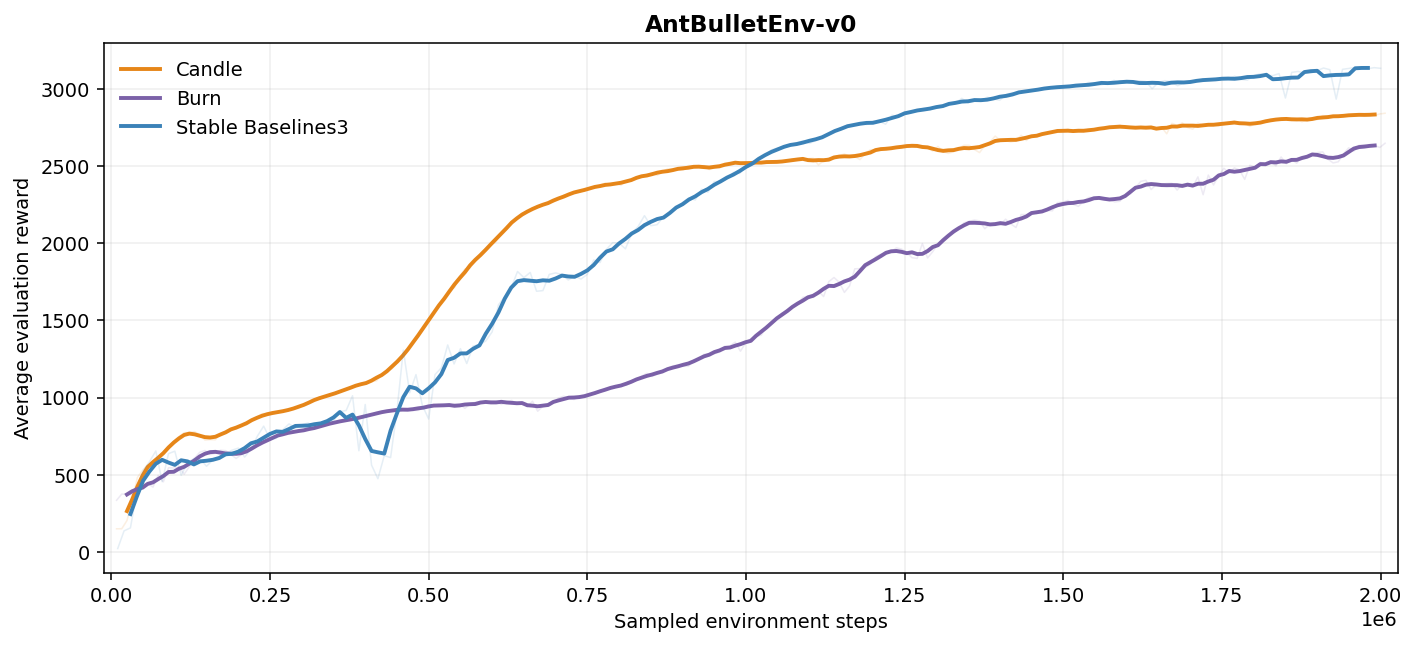
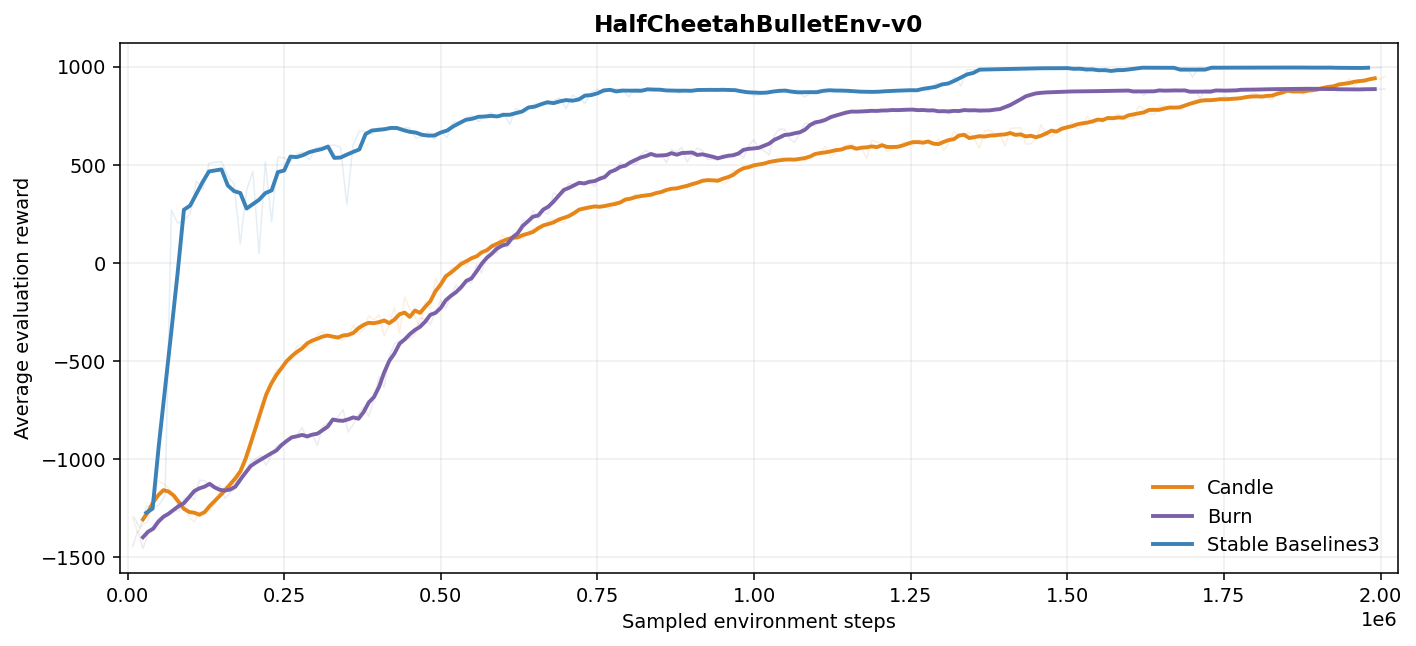
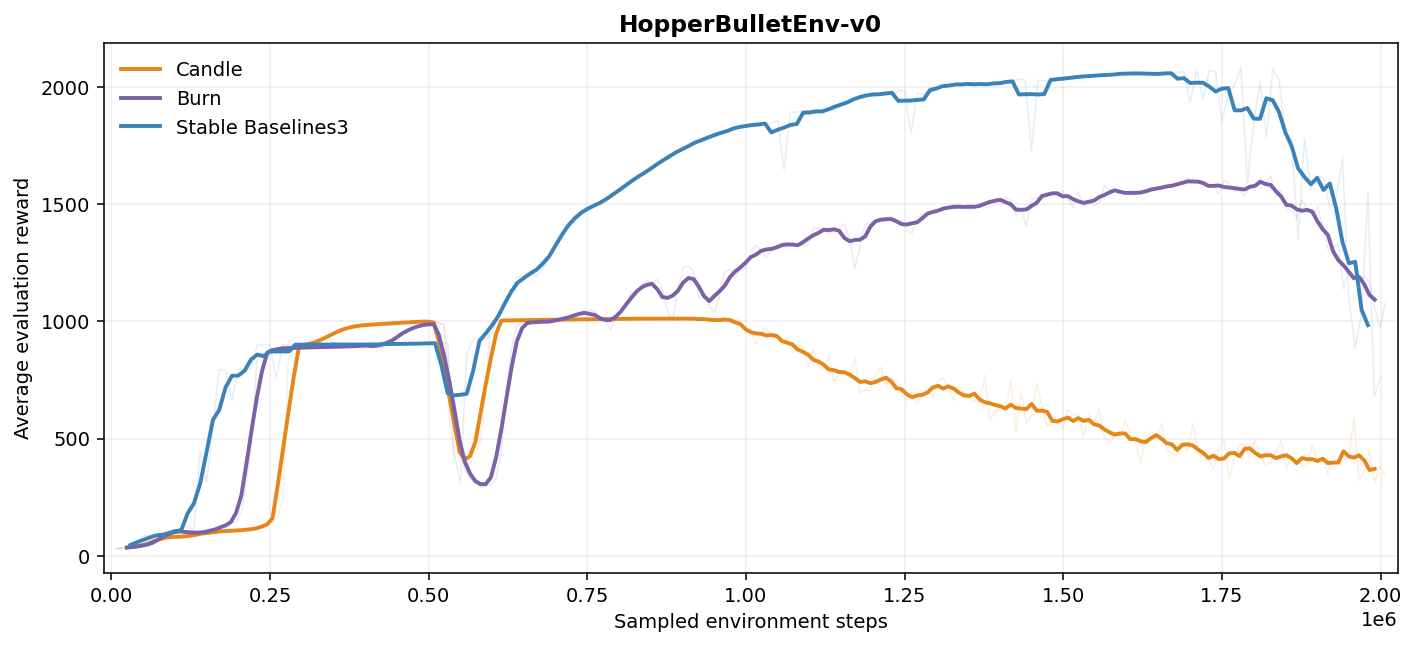
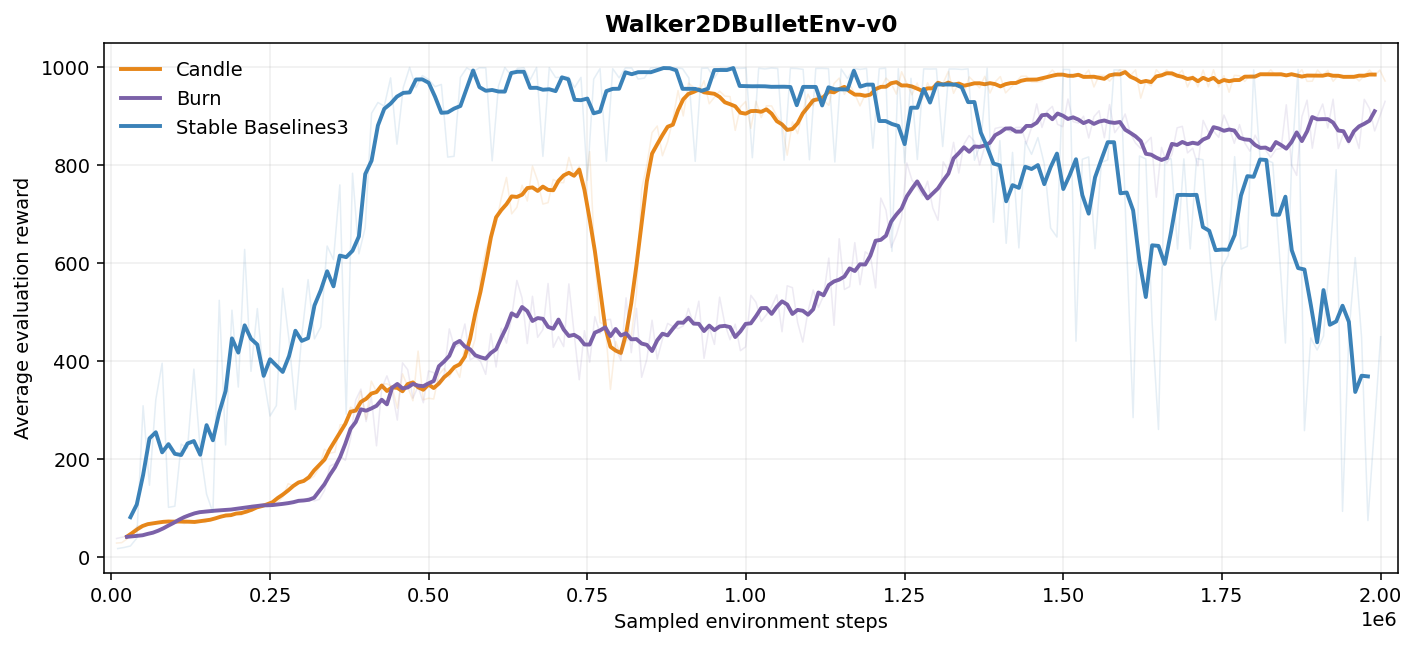
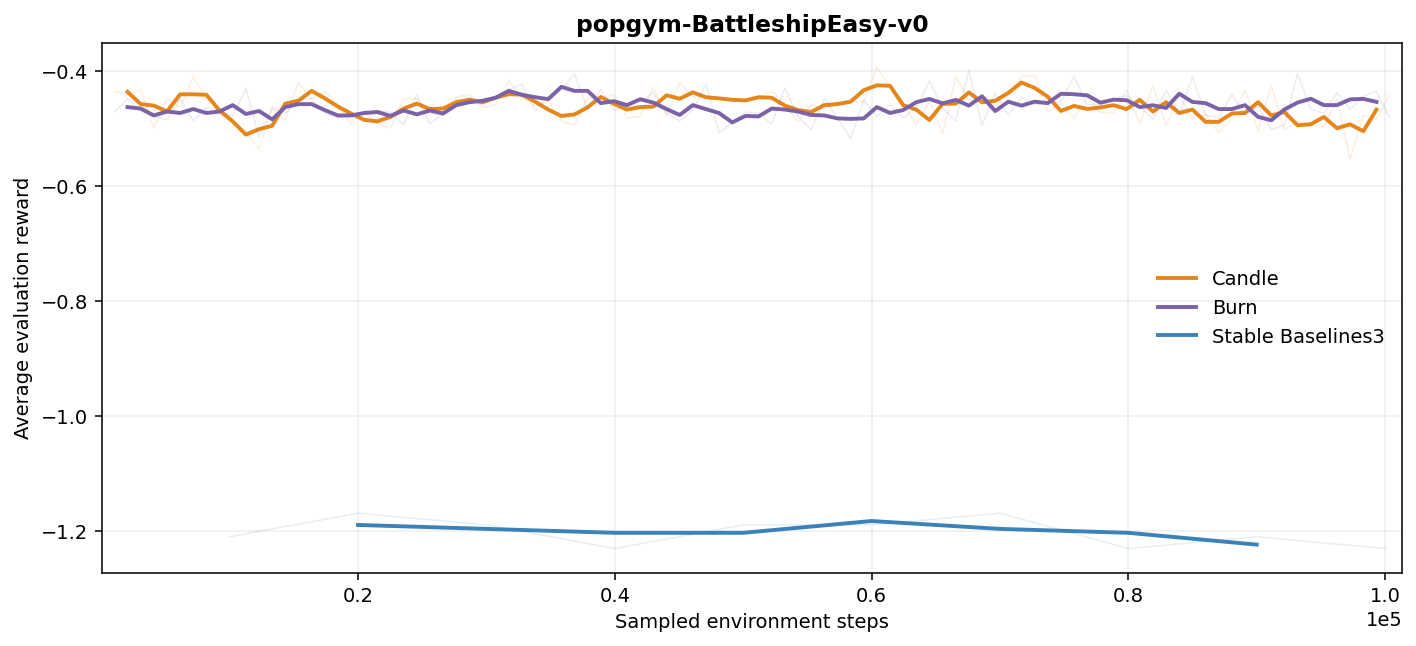
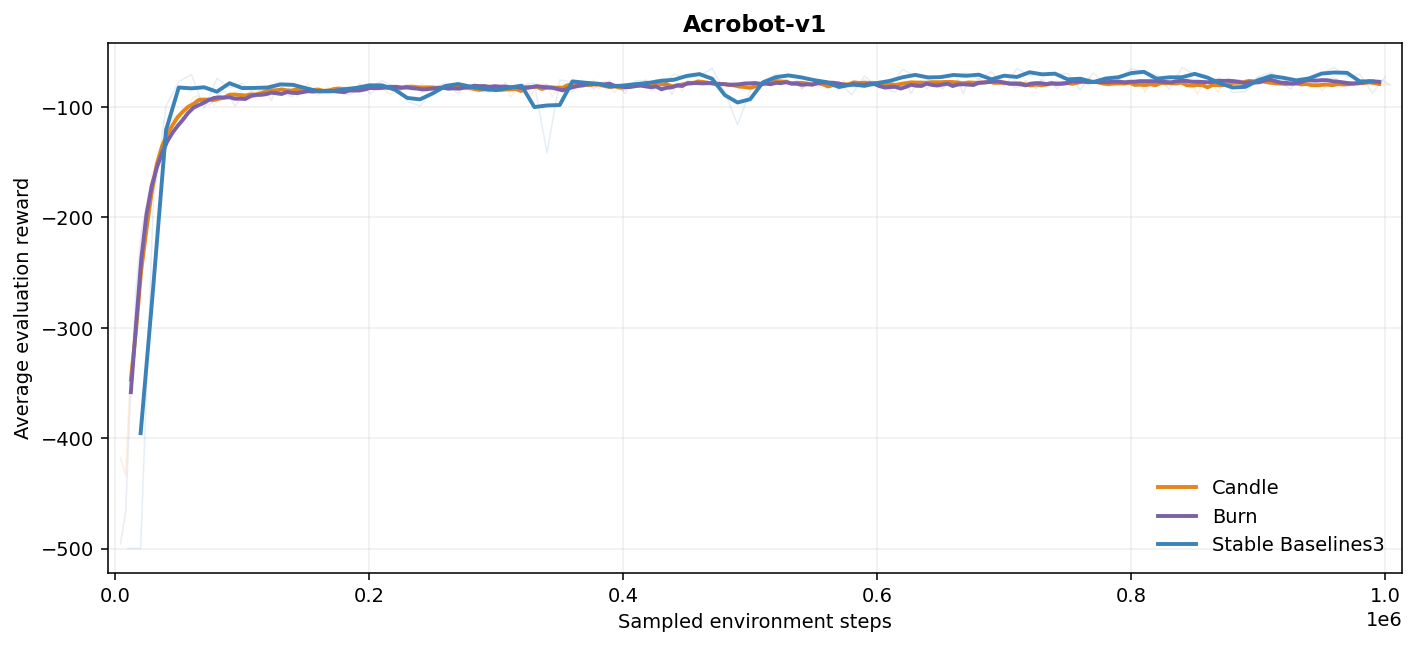
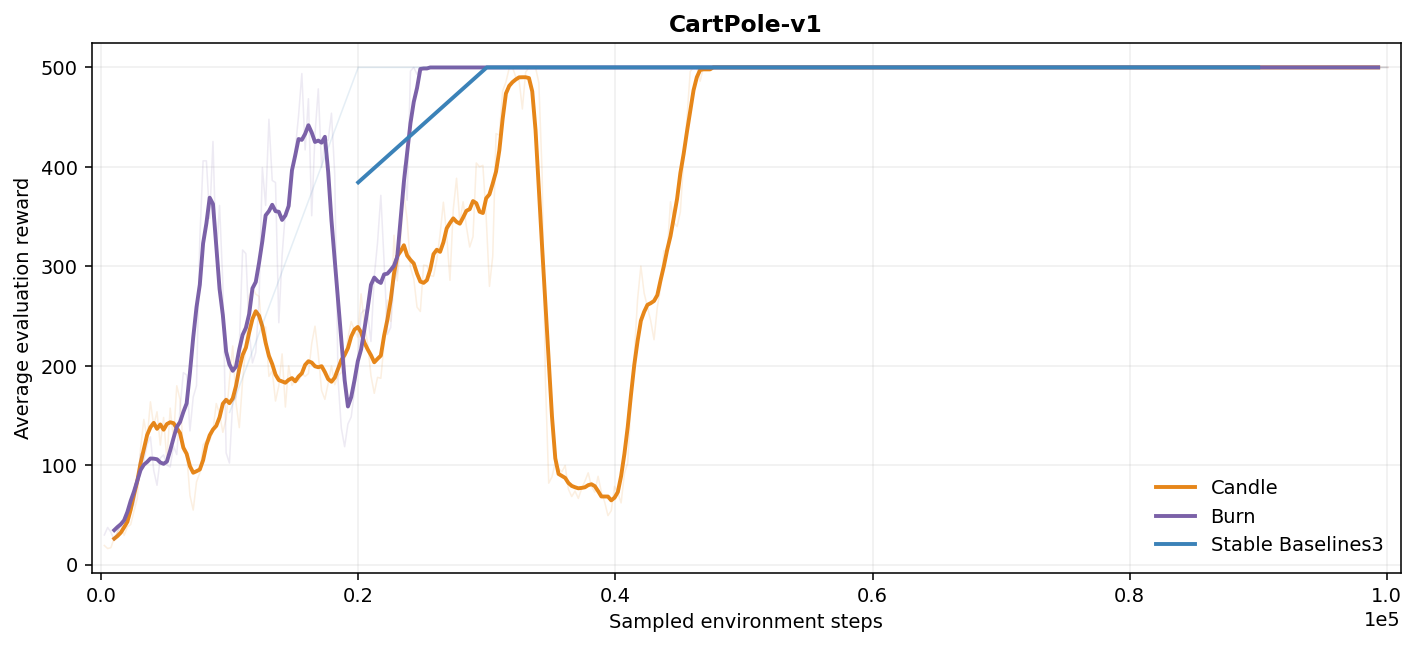
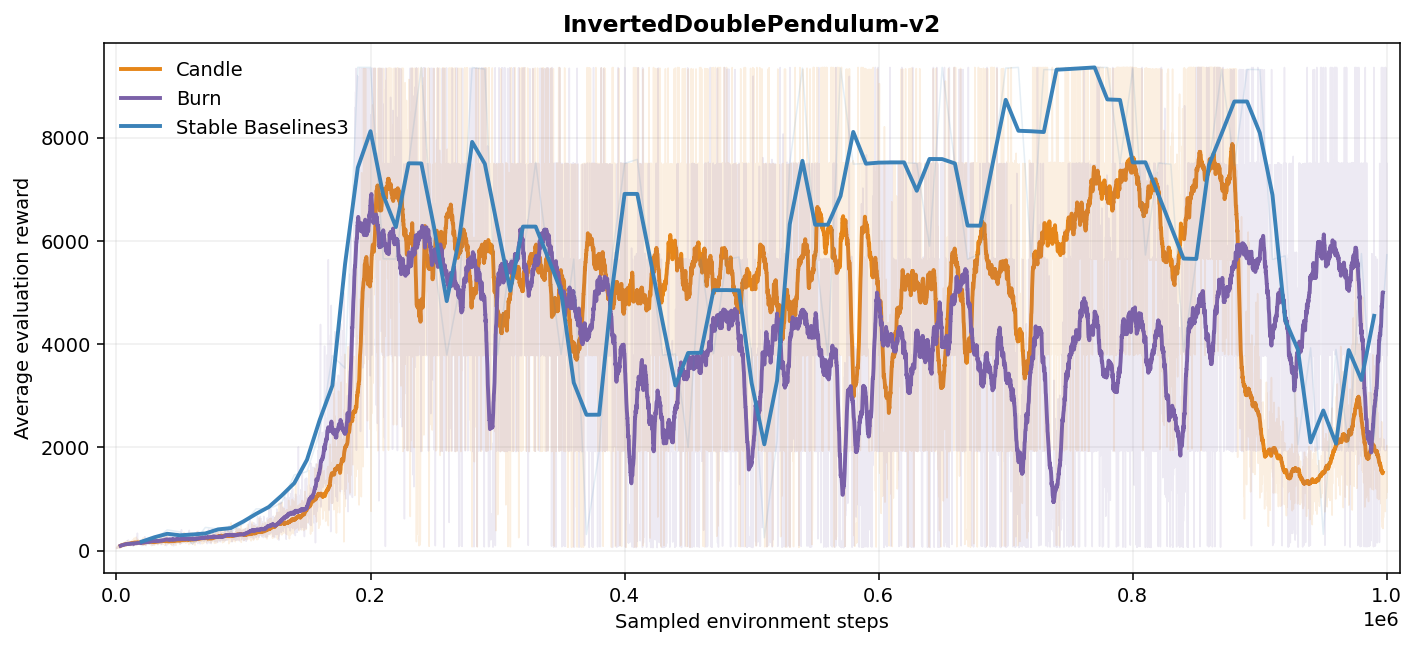
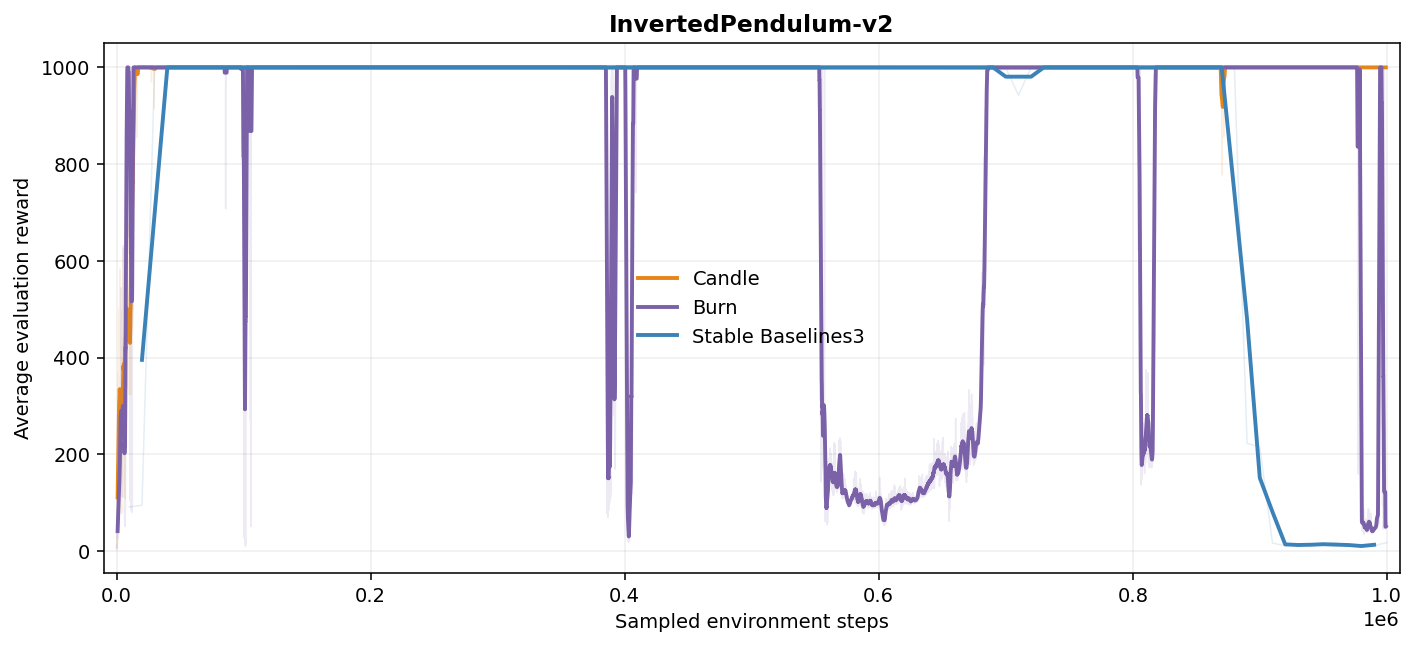
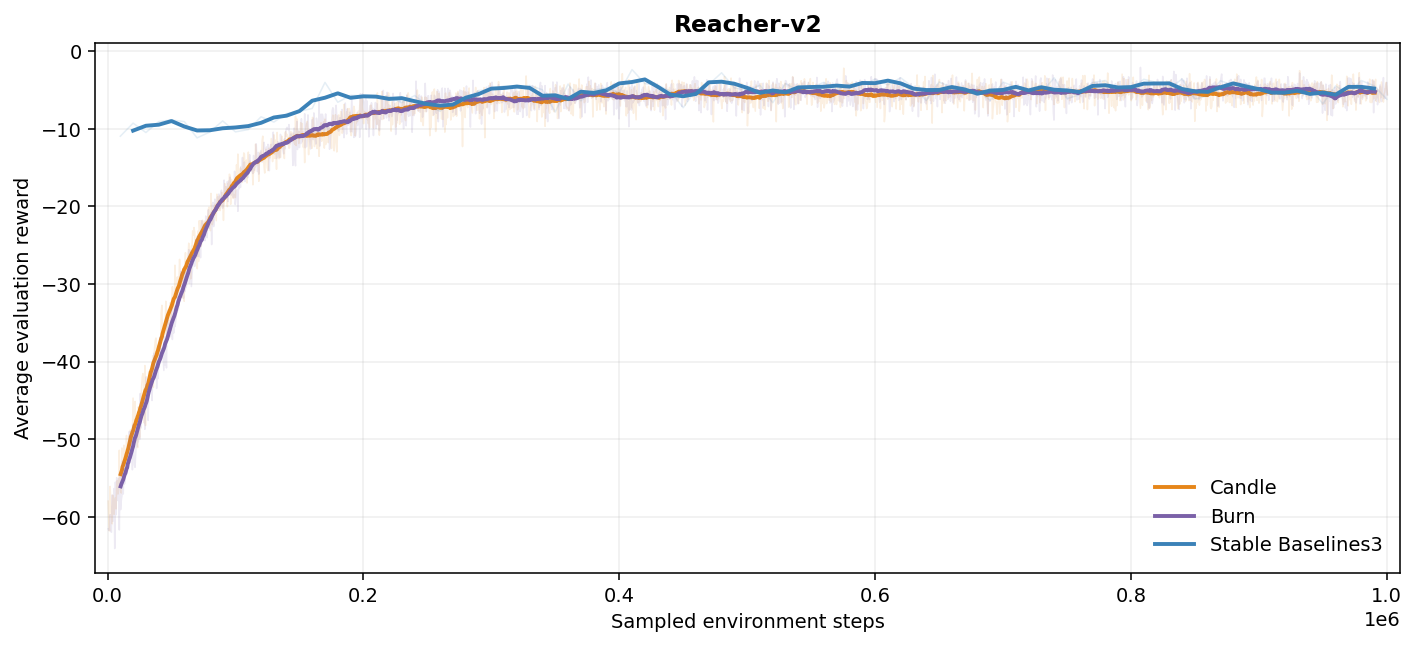
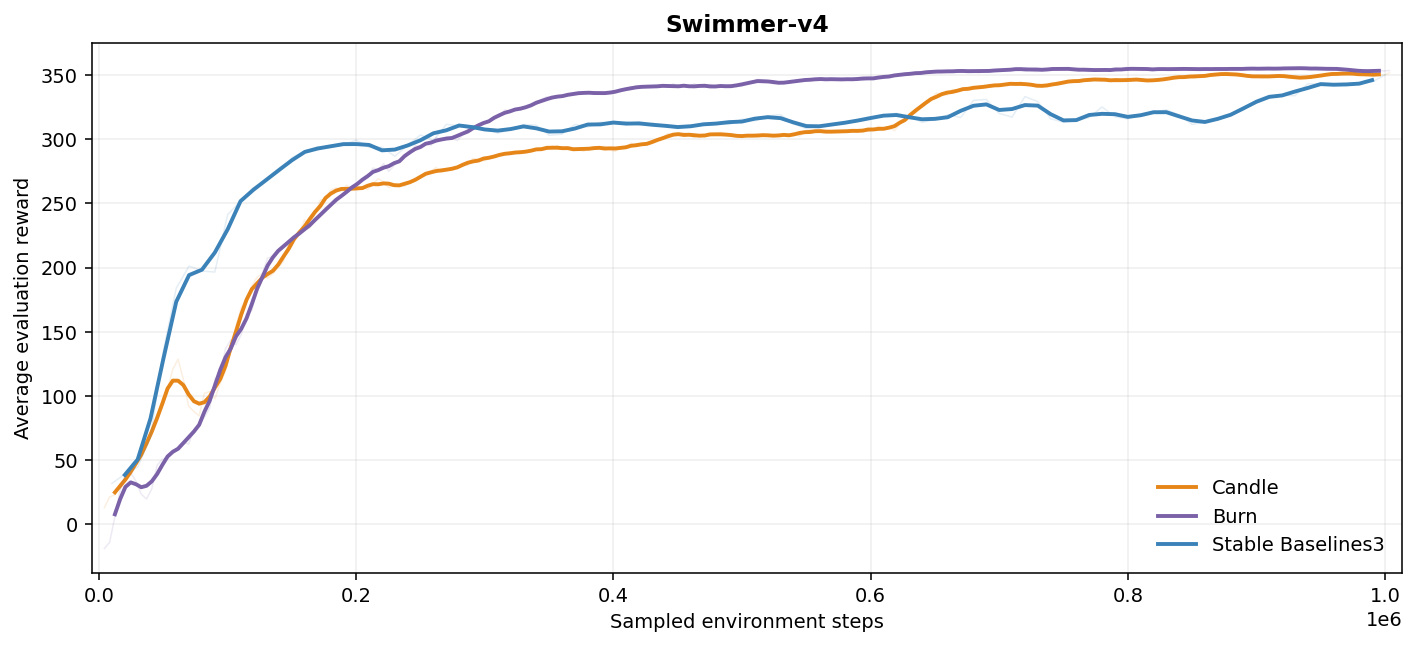
Both r2l backends produce learning curves across the full suite through the same public API and PPO configuration. Many Candle and Burn curves follow similar broad trends, while some environments show substantial differences between the backends and SB3.
All evaluation curves
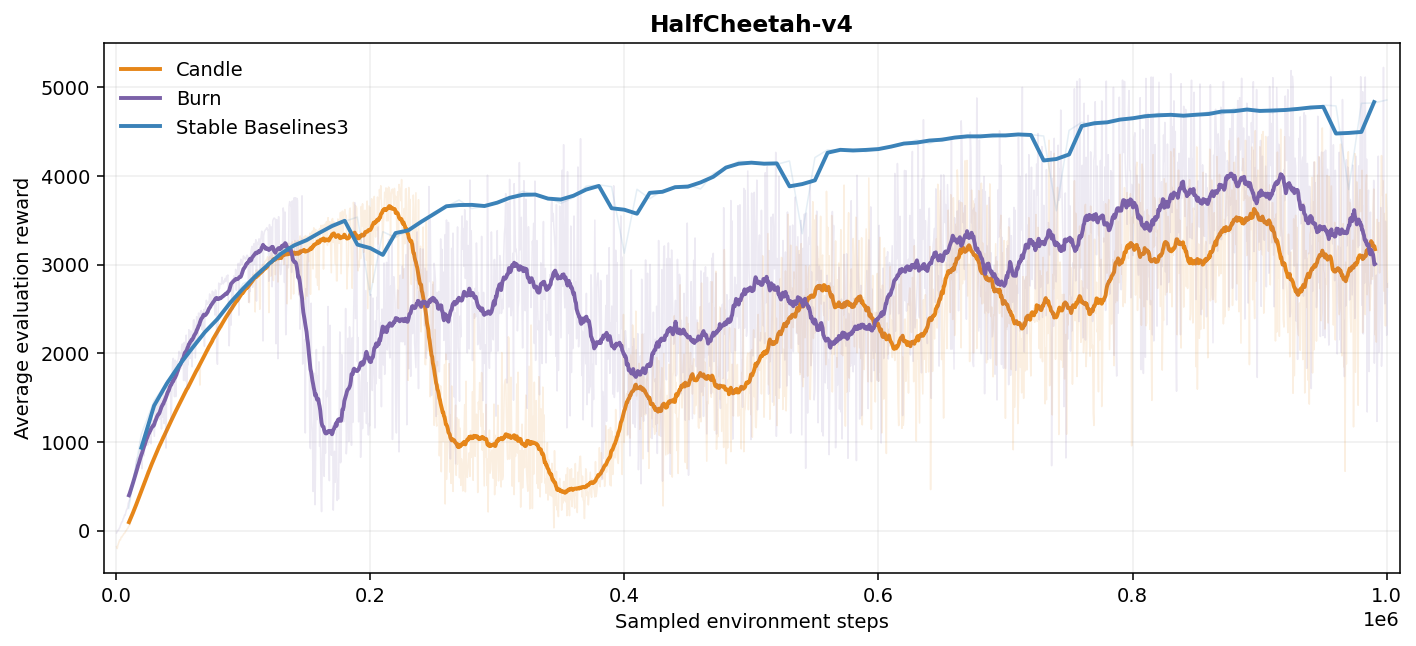
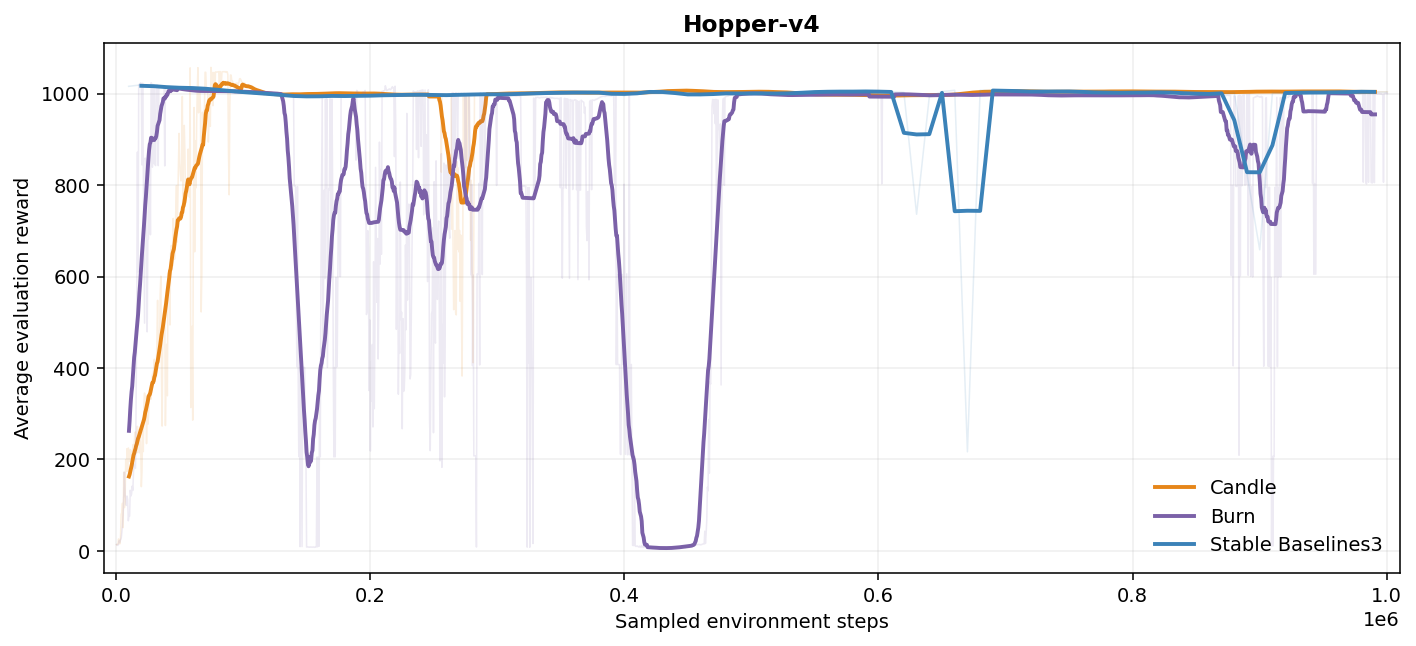
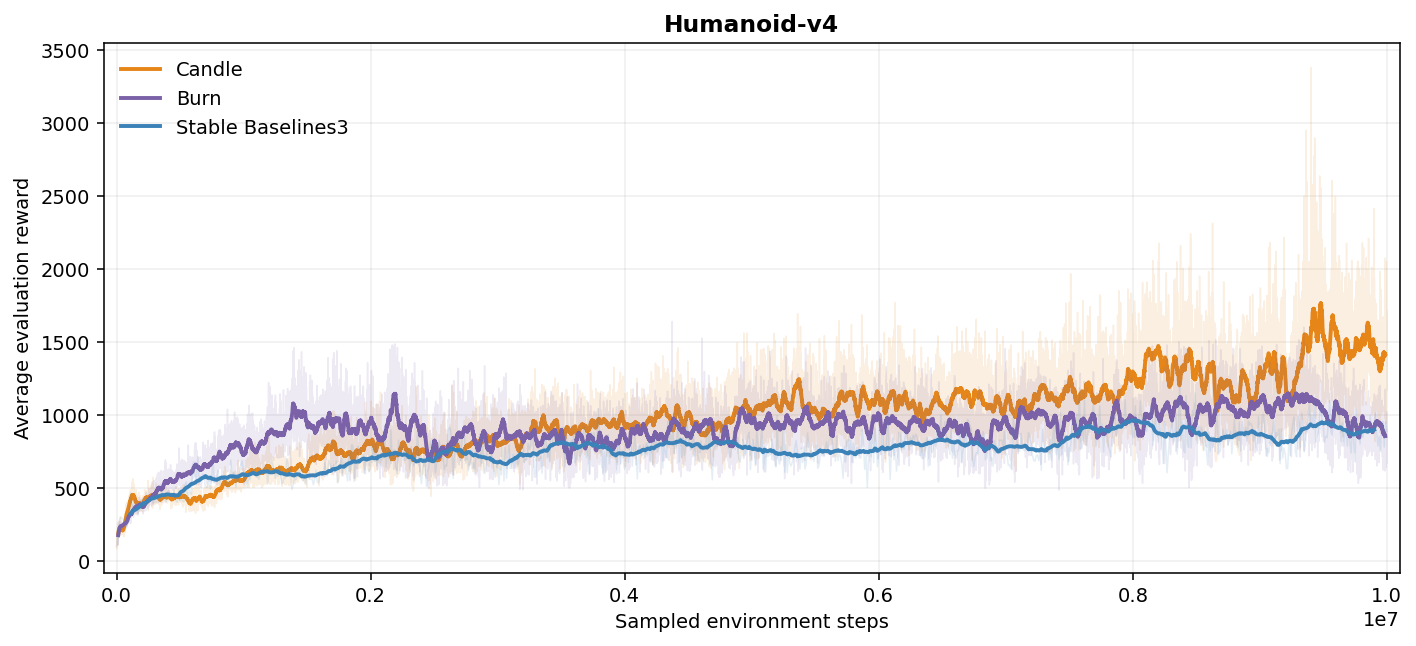
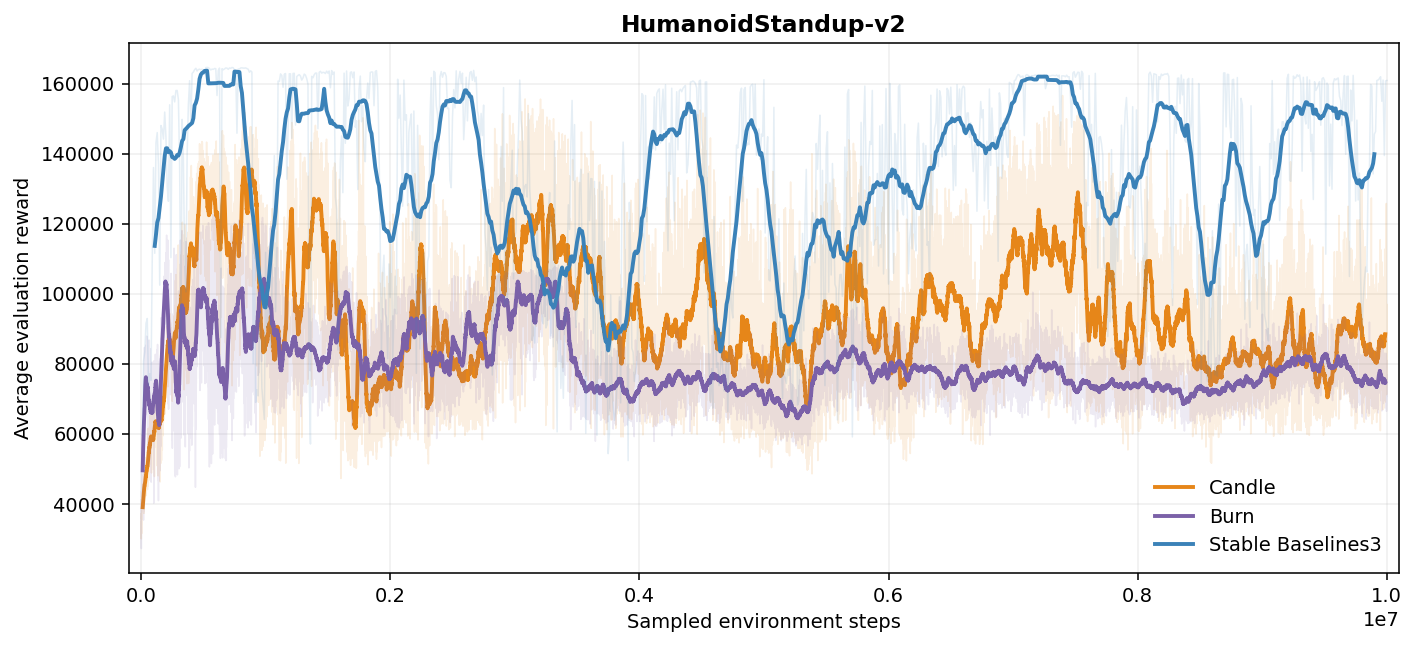
The horizontal axis is the number of environment interactions sampled during
training. Faint lines show the recorded evaluation values and solid lines show
moving averages. Higher reward is better, but reward scales should only be
compared within an environment. The plots are generated by
book/scripts/plot_results.py.
MuJoCo
Ant-v4
HalfCheetah-v4
Hopper-v4
Humanoid-v4
HumanoidStandup-v2
InvertedDoublePendulum-v2
InvertedPendulum-v2
Reacher-v2
Swimmer-v4
Walker2d-v4